diff --git a/README.md b/README.md index f4c7eff..fb84052 100644 --- a/README.md +++ b/README.md @@ -1,19 +1,38 @@ # Distributed Graph Flow

- +

-**(Distributed) Graph Flow** (GF) is a Python toolkit to develop and deploy -Graph Neural Network (**GNN**) models. +

+PyPI +Python +License +Documentation +

+ +**Graph Flow** (DGF) is an open-source Python library to train, evaluate, and +deploy Graph Neural Networks (**GNNs**) on tabular, relational, and temporal +data. It is developed by the Google GNN team, the team behind +[TensorFlow GNN](https://github.com/tensorflow/gnn), and is its successor. + +Graph Flow has two APIs: + +- The **Simple API** is as easy to use as scikit-learn: one function call + trains a GNN model from a graph and a target column, and the resulting + model can be evaluated, used for predictions, and saved. +- The **Advanced API** is a set of composable building blocks (graph IO, + samplers, feature normalizers, and JAX/Flax GNN layers). Like Lego bricks, + you pick the ones you need and assemble them with your own code, including + PyTorch Geometric models. -For more information, check the documentation at https://dgf.readthedocs.io/ +📖 **Documentation:** https://dgf.readthedocs.io/ This is not an officially supported Google product. This project is not eligible for the [Google Open Source Software Vulnerability Rewards Program](https://bughunters.google.com/open-source-security). -## Installation +## 📦 Installation To install DGF from [PyPI](https://pypi.org/project/dgf/), run: @@ -21,33 +40,78 @@ To install DGF from [PyPI](https://pypi.org/project/dgf/), run: pip install dgf -U ``` -Currently, DGF is available on Python 3.11-13, on Linux x86-64. +Graph Flow is available for Python 3.11–3.13 on Linux x86-64. -## 😎 Minimal Usage example +## 🔥 Why Graph Flow? -```python -# Temporary fix for Keras dependency. -import os -os.environ["TF_USE_LEGACY_KERAS"] = "1" +- **Simple API:** Train, evaluate, and save a GNN model in about 10 lines of + Python, without prior GNN experience. +- **Temporal graphs:** Dynamic graphs and time-series features are supported. + Time-aware sampling ensures that a model only sees information available + before the prediction time. +- **Scale:** Train in memory on graphs with up to 1B edges on a single + machine. For larger graphs, the distributed sampler (Apache Beam on Google + Cloud Dataflow) scales to trillions of edges. +- **Advanced API:** Message-passing layers (MPNN, GAT, Graph Transformer), + samplers, and normalizers are independent JAX/Flax building blocks for + custom models. +- **Interoperability:** Convert graphs to PyTorch Geometric, TensorFlow, + TF-GNN, and NetworkX. +- **Deployment:** Run inference in-process in Python, or export models to + TensorFlow SavedModel (e.g., for Vertex AI). + +## 😎 Minimal usage example -# Import (distributed) graph flow +```python import dgf -# Fetch an example graph +# Download an example graph graph, schema = dgf.io.fetch_ogb_graph("arxiv") -# Train a model -model = dgf.learning.train_node_model(graph=graph, schema=schema, target_column="labels") +# Train a GNN model to predict the "labels" feature on the "nodes" nodeset +model = dgf.learning.train_node_model( + graph=graph, + schema=schema, + target_column="labels", + target_nodeset="nodes", +) -# Look at the model +# Inspect training statistics, architecture, and schema model.describe() -# Evaluate the model +# Evaluate quality metrics model.evaluate() -# Make predictions +# Make low-latency predictions in-process model.predict(graph, seed_node_idxs=[0, 1, 2]) -# Save the model for later +# Save the model (architecture, weights, sampling config, training logs, etc.) model.save("/tmp/model") ``` + +
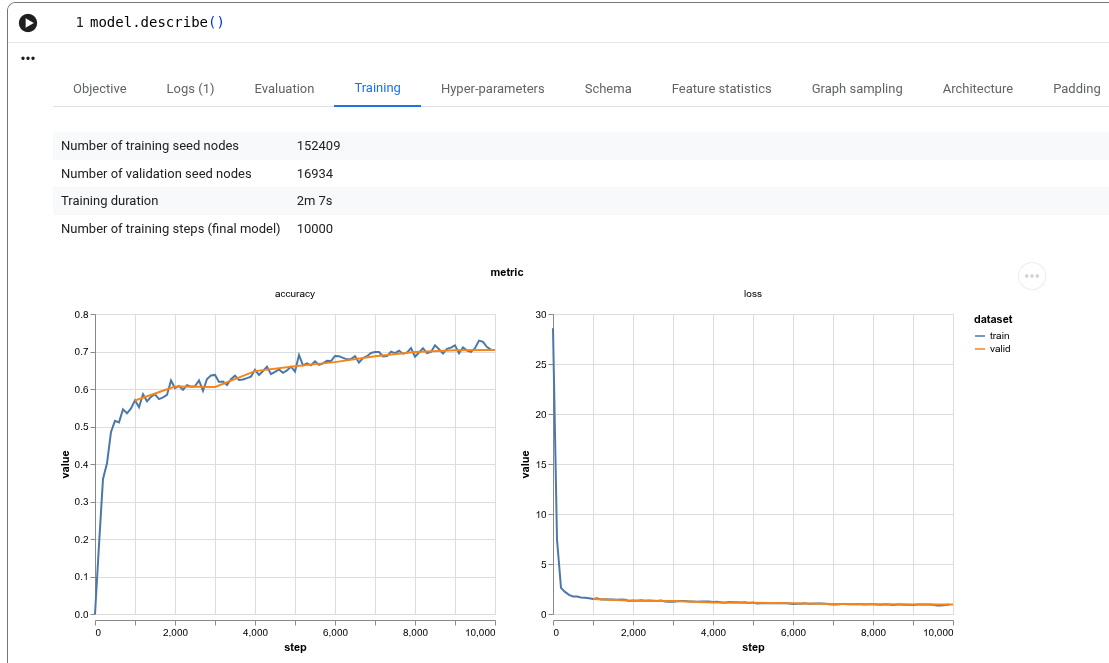
+Output of model.describe() + +Model description + +
+ +
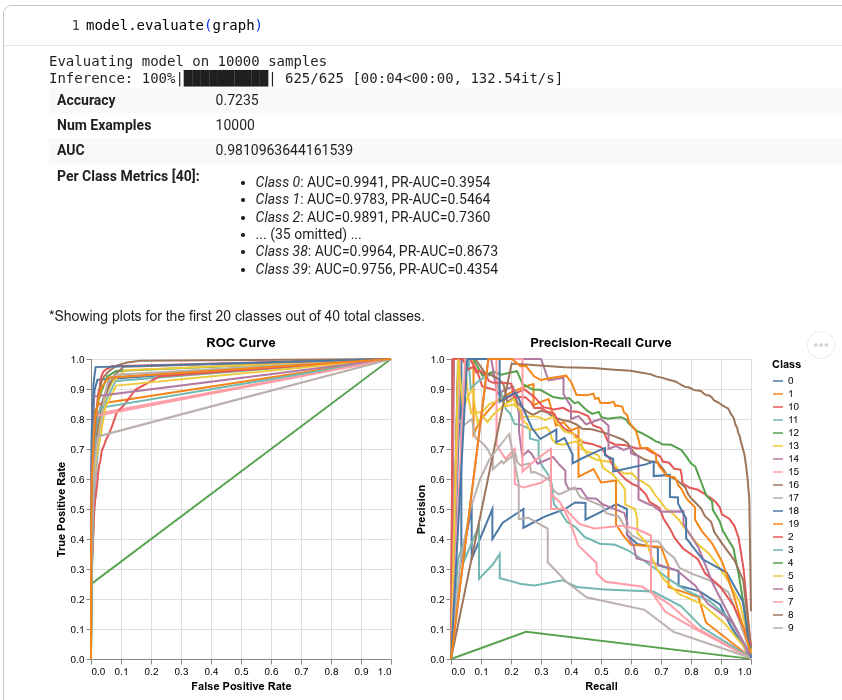
+Output of model.evaluate() + +Model evaluation + +
+ +See the +[Getting Started tutorial](https://dgf.readthedocs.io/en/latest/tutorial/getting_started_simple_api.html) +for the complete walkthrough. + +## 🤗 Need help? + +- Read the [documentation](https://dgf.readthedocs.io/) and the + [Q&A](https://dgf.readthedocs.io/en/latest/qna.html). +- **Bugs & feature requests:** Open a + [GitHub issue](https://github.com/google/distributed_graph_flow/issues). +- **Contact the team:** Email us at + [distributed-graph-flow-contact@google.com](mailto:distributed-graph-flow-contact@google.com). diff --git a/doc/docs/image/logo.png b/doc/docs/image/logo.png index b3cd4dc..03dbc4b 100644 Binary files a/doc/docs/image/logo.png and b/doc/docs/image/logo.png differ diff --git a/doc/docs/image/usage_example_describe.png b/doc/docs/image/usage_example_describe.png new file mode 100644 index 0000000..9439a18 Binary files /dev/null and b/doc/docs/image/usage_example_describe.png differ diff --git a/doc/docs/image/usage_example_evaluate.png b/doc/docs/image/usage_example_evaluate.png new file mode 100644 index 0000000..9552862 Binary files /dev/null and b/doc/docs/image/usage_example_evaluate.png differ diff --git a/doc/docs/index.md b/doc/docs/index.md index a645ad2..6289acc 100644 --- a/doc/docs/index.md +++ b/doc/docs/index.md @@ -1,108 +1,263 @@ +--- +template: home.html +hide: + - toc +--- # -
- -
-**Graph Flow** (Distributed GF, or simply GF) is a Python toolkit to develop and deploy Graph Neural -Network (**GNN**) models. - -DGF is developed by the Google GNN team. - -!!! info - Distributed Graph Flow is in **Pre-GA**. We are actively collaborating with - pilot clients. Contact us if you're interested in learning more or - participating. - -## Installation - -To install DGF from [PyPI](https://pypi.org/project/dgf/), run: +**Graph Flow** (DGF) is an open-source Python library to train, evaluate, and +deploy Graph Neural Networks (GNNs). It is developed by the Google GNN team, the +team behind [TensorFlow GNN](https://github.com/tensorflow/gnn), and is its +successor. + +Graph Flow has two APIs: + +- The **Simple API** is as easy to use as scikit-learn: one function call + trains a GNN model from a graph and a target column, and the resulting + model can be evaluated, used for predictions, and saved. Graph sampling, + feature normalization, and model architecture are configured + automatically. +- The **Advanced API** is a set of composable building blocks (graph IO, + samplers, feature normalizers, and JAX/Flax GNN layers). You pick the ones + you need and assemble them with your own code, including + PyTorch Geometric models. + +## 🔥 Why Graph Flow? + +- **Simple API:** Train, evaluate, and save a GNN model in about 10 lines of + Python, without prior GNN experience. +- **Temporal graphs:** Dynamic graphs and time-series features are supported. + Time-aware sampling ensures that a model only sees information available + before the prediction time. +- **Scale:** Train in memory on graphs with up to 1B edges on a single + machine. For larger graphs, the distributed training scales to trillions of + edges. +- **Advanced API:** Message-passing layers (MPNN, GAT, Graph Transformer), + samplers, and normalizers are independent JAX/Flax building blocks for + custom models. +- **Interoperability:** Convert graphs to PyTorch Geometric, TensorFlow, + TF-GNN, and NetworkX. For example, use Graph Flow to load and sample a + graph, and PyG to train the model + ([example](https://github.com/google/distributed_graph_flow/blob/main/examples/node_classification_pyg.py)). +- **Data sources:** Read graphs from Parquet files, TF-GNN graph samples, + Spanner Graph, BigQuery Graph, and NetworkX. +- **Deployment:** Run inference in-process in Python, or export models to + TensorFlow SavedModel (e.g., for Vertex AI). + +## 🎯 Is Graph Flow right for your problem? + +GNNs are a good fit when your data consists of interconnected entities, for +example multiple tables linked by keys, transactions between accounts, or +time-series events. Tabular models (e.g., gradient boosted trees) ignore these +relations, and LLMs are costly to run on large structured datasets. Typical +tasks are: + +- **Node classification:** Spam, fraud, and abuse detection; bot + classification; account takeover. +- **Node regression:** Hardware failure prediction, latency forecasting, + customer churn. +- **Link prediction:** Recommendation, citation prediction. +- **Node and graph embeddings** *(coming soon)*: Representation learning for + search ranking, clustering, and LLM input. + +## 😎 Simple usage example + +Install Graph Flow from [PyPI](https://pypi.org/project/dgf/) (Python 3.11–3.13, +Linux x86-64): ```shell pip install dgf -U ``` -Currently, DGF is available on Python 3.11-13, on Linux x86-64. - -## 😎 Minimal Usage Example +Then, train a complete node classification GNN model on the +[OGB arXiv](https://ogb.stanford.edu/docs/nodeprop/#ogbn-arxiv) citation graph +in 10 lines of Python (click on **Output** to expand the results): ```python -# Temporary fix for Keras dependency. -import os -os.environ["TF_USE_LEGACY_KERAS"] = "1" - -# Import (distributed) graph flow import dgf -# Fetch an example graph +# Download an example graph graph, schema = dgf.io.fetch_ogb_graph("arxiv") -# Train a model -model = dgf.learning.train_node_model(graph=graph, schema=schema, target_column="labels") - -# Look at the model -model.describe() - -# Evaluate the model -model.evaluate() - -# Make predictions -model.predict(graph, seed_node_idxs=[0, 1, 2]) - -# Save the model for later -model.save("/tmp/model") +# Train a GNN model to predict the "labels" feature on the "nodes" nodeset +model = dgf.learning.train_node_model( + graph=graph, + schema=schema, + target_column="labels", + target_nodeset="nodes", +) ``` -(See results in the -[Getting Started tutorial](tutorial/getting_started_simple_api.ipynb)) - -## 🧭 Getting Started - -- **New to Graph Flow?** Follow the 🧭 - [Getting Started](tutorial/getting_started_simple_api.ipynb) tutorial to - learn how to train a GNN model in 10 lines of code. -- **API Reference:** The 📖 [API](api.md) page provides a comprehensive - overview of all available functions and modules. -- **Advanced Users:** If you are already familiar with JAX or are an advanced - ML user, explore the 🔥 - [Getting Started: Advanced API](tutorial/getting_started_advanced_api.ipynb) - tutorial for an introduction to DGF's low-level API. +??? example "Output" + + ```text + Preparing dataset + Num. training seed nodes: 152409, Num. validation seed nodes: 16934 + Preparing dataset finished in 3.52 seconds + Caching validation dataset finished in 5.67 seconds + Number of cache validation batches: 529 + Training model + Generate first batch to initialize model + Create model variables + ...Tracing model + Create model variables finished in 7.42 seconds + Will validate model every 1000 step(s) + Will checkpoint model every 1000 step(s) + Start training. The first two steps are generally slow. + Training: 10%|â–‰ | 992/10000 [00:18<01:25, 105.02it/s, step=1000, train-accuracy=0.5697, train-loss=1.5092] + Training: 100%|██████████| 10000/10000 [01:49<00:00, 91.32it/s, step=9900, train-accuracy=0.7050, train-loss=0.9234, valid-accuracy=0.7032, valid-loss=0.9513] + Restoring best model parameters with validation loss 0.945846 from step 10000 + Final metrics: {'step': '9900', 'train-accuracy': '0.7050', 'train-loss': '0.9234', 'valid-accuracy': '0.7032', 'valid-loss': '0.9513'} + Training model finished in 117.85 seconds + Final model evaluation + Evaluating model on generator + Evaluation: 100%|██████████| 10000/10000 [00:06<00:00, 1463.66it/s] + ``` -## 🤗 Need help? - -Here are several ways to get support: - -* Check the [Q&A](qna.md) for common questions and answers. -* **Report Issues / Feature Requests:** Create a - [GitHub Issue](https://github.com/google/distributed_graph_flow/issues). -* **Contact the Team:** - * Email us at - [distributed-graph-flow-contact@google.com](mailto:distributed-graph-flow-contact@google.com). - * **[Google Internal]** Join the [GNN User chat](http://go/gnn-user-chat) - or the - [Graph Flow team](https://moma.corp.google.com/team/1437514206756) chat. - -## 🔥 Key features - -High level API: +```python +# Inspect training statistics, architecture, and schema +model.describe() +``` -* **Node prediction:** Train a node prediction model. +??? example "Output" -* **Link prediction:** Train a link prediction model. + ![Model description](image/usage_example_describe.png) -* **Model evaluation:** Get a rich evaluation report of the model. +```python +# Evaluate quality metrics +model.evaluate() +``` -* **Model export to TensorFlow:** Save the model as a TensorFlow SavedModel - compatible with Google VertexAI. +??? example "Output" -Low level API: + ![Model evaluation](image/usage_example_evaluate.png) -* **In-process and semi-distributed graph sampling:** Sample graphs for GNN - training. +```python +# Make low-latency predictions in-process +model.predict(graph, seed_node_idxs=[0, 1, 2]) +``` -* **Data Normalization:** Normalize data for consumption by neural networks. +??? example "Output" + + ```text + array([[7.54999419e-05, 3.81319027e-04, 1.72524105e-05, 1.92803110e-03, + 8.16370904e-01, 2.45856913e-03, 1.42833189e-04, 3.89835302e-04, + 1.02235435e-03, 1.59653846e-05, 1.05817253e-02, 1.66349622e-04, + 2.24696038e-07, 5.67139999e-04, 1.16685828e-06, 1.30570133e-05, + 1.84653066e-02, 1.01524356e-05, 1.19269625e-05, 4.92823659e-04, + 5.76051571e-06, 3.18754552e-04, 1.57974500e-05, 1.38371877e-04, + 1.40396342e-01, 2.21383398e-05, 6.77731412e-04, 5.43191454e-05, + 2.81101861e-03, 1.29758300e-05, 1.40280827e-04, 7.64641154e-05, + 1.21267367e-05, 1.56967496e-06, 4.33137146e-04, 4.30545424e-06, + 1.53830438e-03, 2.04537064e-04, 7.27951203e-07, 2.27046985e-05]], + dtype=float32) + ``` -* **Data Sources:** Support graph formats: Parquet base-graph (Graph Flow - format), TensorFlow GNN sample, Spanner Graph, BigQuery Graph, NetworkX. +```python +# Save the model (architecture, weights, etc.) +model.save("/tmp/model") +``` -* **JAX GNN layers:** Heterogeneous Message Passing GNN, Heterogeneous Graph - Attention Network, Homogenizer. +Check the [Getting Started tutorial](tutorial/getting_started_simple_api.ipynb) +for the complete, interactive walkthrough. + +## 🧩 Advanced API: composable building blocks + +The Simple API is assembled from the building blocks of the Advanced API, and +you can use them directly. Each block does one thing (load, +sample, normalize, or run message passing), and blocks can be combined with +each other or with other frameworks. For example, you can use Graph Flow to +load, sample, and normalize a graph, and train a PyTorch Geometric or JAX/Flax +model on the result: + +=== "PyTorch Geometric" + + ```python + import dgf + + graph, schema = dgf.io.fetch_ogb_graph("mag") + + # Graph Flow: Sample 2-hop neighborhoods around the seed nodes + sampler = dgf.sampling.create_sampler( + graph=graph, + schema=schema, + plan=dgf.sampling.SimpleSamplingConfig( + seed_nodeset="paper", num_hops=2, hop_width=10, reverse=True + ), + batch_size=256, + ) + merger = dgf.transform.GraphMerger(schema=schema, padding=None, sentinel_offset=False) + batch, offsets = merger(sampler.sample(seed_node_idxs)) + + # Graph Flow: Normalize the features automatically + normalizer = dgf.transform.auto_normalize(schema=schema, stats=feature_stats) + batch = normalizer.normalize_numpy(batch) + + # PyG: Convert to HeteroData, and train any PyG model + data = dgf.convert.graph_to_pyg_data(batch, normalizer.output_schema()) + logits = pyg_model(data.x_dict, data.edge_index_dict, offsets["paper"]) + ``` + + See the complete + [PyG example](https://github.com/google/distributed_graph_flow/blob/main/examples/node_classification_pyg.py). + +=== "JAX / Flax" + + ```python + import dgf + import flax.linen as nn + + class Model(nn.Module): + schema: dgf.data.GraphSchema + num_classes: int + + @nn.compact + def __call__(self, graph, seed_node_idxs, training): + # Embed the raw features of each nodeset + embedder = dgf.jax.layers.EmbedGraphConfig() + graph = embedder.make(schema=self.schema)(graph, training=training) + hidden_schema = embedder.output_schema(self.schema) + + # Heterogeneous message passing + for _ in range(2): + conv = dgf.jax.layers.HeterogeneousGraphConvolutionConfig(dims=128) + graph = conv.make(hidden_schema)(graph, training=training) + + # Classify the seed nodes + embeddings = graph.node_sets["nodes"].features["embedding"][seed_node_idxs] + return nn.Dense(self.num_classes)(embeddings) + ``` + + See the [Advanced API tutorial](tutorial/getting_started_advanced_api.ipynb) + for the complete training loop. + +## 🧭 Getting started & resources + +- **Getting Started:** The + [Getting Started tutorial](tutorial/getting_started_simple_api.ipynb) + trains a first GNN model with the Simple API. +- **Advanced API:** The + [Advanced API tutorial](tutorial/getting_started_advanced_api.ipynb) builds + a custom GNN from the JAX/Flax building blocks. +- **Distributed sampling:** The + [Offline Distributed Sampler tutorial](tutorial/gcp_offline_distributed_sampler.ipynb) + samples large graphs on Google Cloud Dataflow. +- **API reference:** The [API documentation](api.md) lists all modules and + functions. +- **Examples:** End-to-end + [example scripts](https://github.com/google/distributed_graph_flow/tree/main/examples), + including training a PyG model. +- **Q&A:** The [Q&A](qna.md) covers the relation to TF-GNN, supported + formats, and large graphs. + +## 🤗 Community & support + +- **Bugs and feature requests:** Open a + [GitHub issue](https://github.com/google/distributed_graph_flow/issues). +- **Contact:** Email the team at + [distributed-graph-flow-contact@google.com](mailto:distributed-graph-flow-contact@google.com). +- **Release notes:** See the [Changelog](changelog.md). +- **Googlers:** See [go/graph-flow](http://go/graph-flow) for the internal + documentation. + +This is not an officially supported Google product. diff --git a/doc/docs/qna.md b/doc/docs/qna.md index e345e3a..75b5ca1 100644 --- a/doc/docs/qna.md +++ b/doc/docs/qna.md @@ -2,17 +2,89 @@ ## What are Graph Neural Networks? -Graph Neural Networks (GNNs) are a class of machine learning methods designed to perform inference on data described by graphs, or on relational data in general. +Graph Neural Networks (GNNs) are a class of machine learning methods designed to +perform inference on data described by graphs, or on relational data in general. + +## Is Graph Flow right for my problem? + +If your data contains multiple interconnected tables, entities, transactions, or +time-series events, standard tabular ML (e.g., gradient boosted trees) ignores +the graph topology, while LLMs can be expensive and ungrounded. Graph Flow is +well suited for node classification (e.g., fraud or abuse detection), node +regression (e.g., failure prediction, churn), and link prediction (e.g., +recommendation, entity resolution). + +## What about temporal data? + +While academic GNNs mostly focus on static graphs, Graph Flow extends GNNs to +full time-aware modeling. For example, Graph Flow supports dynamic graphs, +time-series features, and time-aware training and sampling (to avoid future +leakage). ## Should I use Graph Flow or TensorFlow GNN? -**You should use Graph Flow:** Graph Flow (GF) is the recommended toolkit from the Google GNN team for developing and deploying GNN models. +**You should use Graph Flow.** Both products are developed by the same team. +Graph Flow is a significant rewrite and improvement of TF-GNN for JAX, with +fundamental usability, efficiency, and quality improvements. It offers a +Simple API that makes GNNs accessible to both experts and ML novices, and an +Advanced API of composable building blocks for researchers. + +TensorFlow GNN is deprecated, and Graph Flow should be used for all new +projects. Graph Flow can read and write TF-GNN formats (graphs and graph +samples), and can export models as TensorFlow SavedModels, so migrating +pipelines is smooth. + +## What are the supported graph file formats? + +Graph Flow supports several file formats for reading and writing graphs: -Graph Flow is designed to simplify GNN development. It is JAX-first but library-agnostic, offering high-level APIs that make GNNs accessible to both experts and ML novices. If you have legacy TF-GNN data or models, Graph Flow provides converters to import/export TF-GNN formats, ensuring a smooth transition. +1. **GF Graph (recommended)**: The primary and most efficient format. It uses a + directory with `metadata.json`, `schema.json`, and Parquet files for the + nodesets and edgesets. Parquet is efficient and compatible with most cloud + and open-source tools. See the [Graph file format](file_formats.md) guide. +2. **TF Graph Samples**: TFRecord files containing serialized + `tensorflow.Example` protos following the TF-GNN conventions. This format is + well suited to represent a large collection of small graph samples. + +Graph Flow can also read graphs from Spanner Graph, BigQuery Graph, and +NetworkX. + +## What are the supported in-memory graph formats? + +Graph Flow provides several in-memory representations in the `dgf.data` module: + +* `dgf.data.InMemoryGraph`: The primary representation, storing data in NumPy + arrays. If your graph is small (less than 1B edges), you can directly create + it in this format. +* `dgf.data.JaxInMemoryGraph`: Stores data in JAX arrays, supporting JAX + compilation (JIT) for message-passing operations. +* `dgf.data.TFInMemoryGraph`: Stores data in TensorFlow tensors, used for + SavedModel serialization. +* `dgf.beam.data.Graph`: A distributed representation using Apache Beam for + large-scale graph processing. + +See the [Graph in-memory objects](graph_formats.md) guide for details. ## How does Graph Flow handle large-scale graphs? -For graphs that exceed the memory of a single machine, Graph Flow provides: +Graphs with up to ~1B edges can be sampled in memory, during training, on a +single machine. + +For larger graphs, it is more efficient to compute graph samples before +training rather than during training. Once computed, the samples can directly +be consumed by the Simple API with +`graph_format="PATH_TF_SAMPLE_TF_RECORD"`. Graph Flow provides two tools to +compute these samples: + +* **Offline distributed sampler**: Distributes both the compute and the graph + topology, scaling to trillions of edges. It runs as an Apache Beam pipeline + on Google Cloud Dataflow. See the + [Offline Distributed Sampler (GCP)](tutorial/gcp_offline_distributed_sampler.ipynb) + tutorial. +* **Offline semi-distributed sampler**: Runs the in-process sampling algorithm + on the graph topology (in parallel across workers) with distributed feature + aggregation. Scales up to ~100B edges. Implemented with Apache Beam (Python) + and C++. See the + [example](https://github.com/google/distributed_graph_flow/blob/main/examples/create_graph_samples_semi_distributed_v2.py). -* **Semi-distributed sampling**: Using Apache Beam, the graph topology is loaded into memory, and feature aggregation is distributed via a MapReduce-like pipeline. Allows scaling up to 100B edges. -* **Distributed sampling**: Not yet available in public package. +For online inference, Graph Flow can sample graphs directly from Spanner Graph. diff --git a/doc/docs/style/extra.css b/doc/docs/style/extra.css index c05488a..82349e4 100644 --- a/doc/docs/style/extra.css +++ b/doc/docs/style/extra.css @@ -146,3 +146,173 @@ h1#_1 { margin-left: 0.2em; opacity: 0.7; } + +/* Collapsible "Output" blocks: keep long training logs readable. */ +.md-typeset details.example pre { + max-height: 30em; + overflow: auto; + white-space: pre !important; +} + +/* ------------------------------------------------------------------------- */ +/* Brand colors (from the Graph Flow logo). */ +/* ------------------------------------------------------------------------- */ + +:root { + --gf-blue: #4285f4; + --gf-red: #ea4335; + --gf-yellow: #fbbc04; + --gf-green: #34a853; +} + +/* ------------------------------------------------------------------------- */ +/* Home page hero (see overrides/home.html). */ +/* ------------------------------------------------------------------------- */ + +.gf-hero { + background: var(--md-code-bg-color); + border: 1px solid var(--md-default-fg-color--lightest); + border-radius: 1rem; + margin: 0.6rem 0 1.6rem; +} + +.gf-hero__inner { + display: flex; + align-items: center; + gap: 1.5rem; + padding: 1.6rem 1.8rem; +} + +.gf-hero__text { + flex: 1 1 60%; +} + +.gf-hero__title { + margin: 0 0 0.6rem; + font-size: 1.3rem; + font-weight: 700; + line-height: 1.3; + color: var(--md-default-fg-color); +} + +.gf-hero__subtitle { + max-width: 30rem; + margin: 0 0 1.1rem; + font-size: 0.8rem; + line-height: 1.6; + color: var(--md-default-fg-color--light); +} + +.gf-hero__buttons { + display: flex; + flex-wrap: wrap; + gap: 0.5rem; + margin-bottom: 0.9rem; +} + +.gf-button { + display: inline-flex; + align-items: center; + gap: 0.45rem; + padding: 0.4rem 0.9rem; + border: 1px solid var(--md-default-fg-color--lighter); + border-radius: 0.3rem; + font-size: 0.7rem; + font-weight: 600; + color: var(--md-default-fg-color) !important; + background: var(--md-default-bg-color); + transition: border-color 0.15s; +} + +.gf-button svg { + width: 1.1em; + height: 1.1em; + fill: currentColor; +} + +.gf-button:hover { + border-color: var(--gf-blue); +} + +.gf-button--primary { + border-color: transparent; + color: #fff !important; + background: var(--gf-blue); +} + +.gf-install { + display: inline-flex; + align-items: center; + gap: 0.6rem; + padding: 0.35rem 0.8rem; + border: 1px solid var(--md-default-fg-color--lightest); + border-radius: 0.5rem; + font-size: 0.7rem; + color: var(--md-default-fg-color--light); + background: var(--md-default-bg-color); + cursor: pointer; +} + +.gf-install code { + padding: 0; + font-size: inherit; + color: var(--md-code-fg-color); + background: none; +} + +.gf-install__prompt { + font-family: var(--md-code-font-family); + opacity: 0.5; +} + +.gf-install__icon svg { + display: block; + width: 1rem; + height: 1rem; + fill: currentColor; +} + +.gf-install__icon--done, +.gf-install--copied .gf-install__icon--copy { + display: none; +} + +.gf-install--copied .gf-install__icon--done { + display: block; + color: var(--gf-green); +} + +.gf-hero__image { + flex: 0 1 35%; + text-align: center; +} + +.gf-hero__image img { + width: 100%; + max-width: 13rem; +} + +@media screen and (max-width: 60em) { + .gf-hero__inner { + flex-direction: column-reverse; + text-align: center; + padding: 1.4rem 1rem; + } + + .gf-hero__title { + font-size: 1.3rem; + } + + .gf-hero__subtitle { + margin-left: auto; + margin-right: auto; + } + + .gf-hero__buttons { + justify-content: center; + } + + .gf-hero__image img { + max-width: 9rem; + } +} diff --git a/doc/mkdocs.yml b/doc/mkdocs.yml index b4f3024..b2aa309 100644 --- a/doc/mkdocs.yml +++ b/doc/mkdocs.yml @@ -1,19 +1,29 @@ site_name: Distributed Graph Flow +site_description: >- + Build, train, evaluate, and deploy Graph Neural Networks on tabular, + relational, and temporal data with JAX. site_url: https://dgf.readthedocs.io/ -theme: readthedocs use_directory_urls: false repo_url: https://github.com/google/distributed_graph_flow repo_name: google/distributed_graph_flow +copyright: Copyright © Google LLC. Licensed under the Apache License 2.0. theme: name: material + custom_dir: overrides favicon: image/icon_128.png logo: image/icon_128.png font: text: Roboto + icon: + repo: fontawesome/brands/github features: - search.suggest + - search.highlight - navigation.expand + - navigation.top + - navigation.footer + - content.code.copy palette: - scheme: default primary: white @@ -38,6 +48,15 @@ markdown_extensions: - pymdownx.details - pymdownx.superfences - attr_list + - md_in_html + - pymdownx.highlight: + anchor_linenums: true + - pymdownx.inlinehilite + - pymdownx.tabbed: + alternate_style: true + - pymdownx.emoji: + emoji_index: !!python/name:material.extensions.emoji.twemoji + emoji_generator: !!python/name:material.extensions.emoji.to_svg plugins: - search @@ -80,7 +99,7 @@ nav: - In-memory graph: tutorial/in_memory_graph.ipynb - In-process Sampler: tutorial/sampler.ipynb - Offline Distributed Sampler (GCP): tutorial/gcp_offline_distributed_sampler.ipynb - - Normaliers: tutorial/normalizer.ipynb + - Normalizers: tutorial/normalizer.ipynb - Guides: - Graph file format: file_formats.md - Graph in-memory objects: graph_formats.md @@ -90,6 +109,16 @@ extra: analytics: provider: google property: G-B6NFSCCG1B + social: + - icon: fontawesome/brands/github + link: https://github.com/google/distributed_graph_flow + name: GitHub + - icon: fontawesome/brands/python + link: https://pypi.org/project/dgf/ + name: PyPI + - icon: fontawesome/solid/envelope + link: mailto:distributed-graph-flow-contact@google.com + name: Contact the team watch: - ../CHANGELOG.md diff --git a/doc/overrides/home.html b/doc/overrides/home.html new file mode 100644 index 0000000..d73c2b8 --- /dev/null +++ b/doc/overrides/home.html @@ -0,0 +1,52 @@ +{# + Landing page template for the Graph Flow documentation home page. +#} +{% extends "main.html" %} + +{% block content %} +
+
+
+
+ A Python library for Graph Neural Networks +
+

+ Build, train, evaluate, and deploy GNNs on tabular, relational, and + temporal data in 10 lines of Python. Developed by the Google GNN team. +

+ + +
+
+ Graph Flow logo +
+
+
+ {{ super() }} +{% endblock %} diff --git a/setup.py b/setup.py index 876efb3..b0964f7 100644 --- a/setup.py +++ b/setup.py @@ -42,10 +42,11 @@ def is_pure(self): description="Distributed Graph Flow", long_description=open("README.md").read(), long_description_content_type="text/markdown", - url="https://github.com/google/dgf", + url="https://github.com/google/distributed_graph_flow", project_urls={ - "Source": "https://github.com/google/dgf.git", - "Tracker": "https://github.com/google/dgf/issues", + "Documentation": "https://dgf.readthedocs.io/", + "Source": "https://github.com/google/distributed_graph_flow.git", + "Tracker": "https://github.com/google/distributed_graph_flow/issues", }, entry_points={ "console_scripts": [